Popular ones
| Type | Name | Formula | Common usage |
|---|
| Non-gated | ReLU | ReLU(x)=max(0,x) | Older Transformer FFNs |
| Non-gated | GELU | GELU(x)=xΦ(x) | BERT, GPT-2, GPT-3-style models |
| Non-gated | SiLU / Swish | SiLU(x)=xσ(x) | Used directly in some modern networks |
| Non-gated | Squared ReLU | ReLU2(x)=max(0,x)2 | Used in some newer architectures |
| Gated | GLU | σ(xWg)⊙(xWu) | Original gated linear unit |
| Gated | ReGLU | ReLU(xWg)⊙(xWu) | GLU variant |
| Gated | GEGLU | GELU(xWg)⊙(xWu) | T5-family / some encoder-decoder models |
| Gated | SwiGLU | SiLU(xWg)⊙(xWu) | Very common in modern LLMs: Llama, Mistral, Qwen, etc. |
Non-gated FFN
FFN(x)=f(xW1)W2
Example with GELU:
FFN(x)=GELU(xW1)W2
Gated FFN
FFN(x)=[f(xWg)⊙(xWu)]Wd
For SwiGLU specifically:
FFN(x)=[SiLU(xWg)⊙(xWu)]Wd
A useful modern-LLM summary is:
Older GPT/BERT→GELU
Modern decoder LLMs→SwiGLU
And the key naming pattern is:
ReLU→ReGLU
GELU→GEGLU
SiLU/Swish→SwiGLU
Not so popular ones
| Name | Formula | Common usage |
|---|
| Sigmoid | σ(x)=1+e−x1 | Gates, not usually standalone FFN activation |
| Tanh | tanh(x)=ex+e−xex−e−x | Rare in modern transformer FFNs |
| Leaky ReLU | max(x,αx) | Rare in LLMs |
| Squared ReLU | ReLU2(x)=max(0,x)2 | Some newer architectures |
| Mish | xtanh(ln(1+ex)) | Rare |
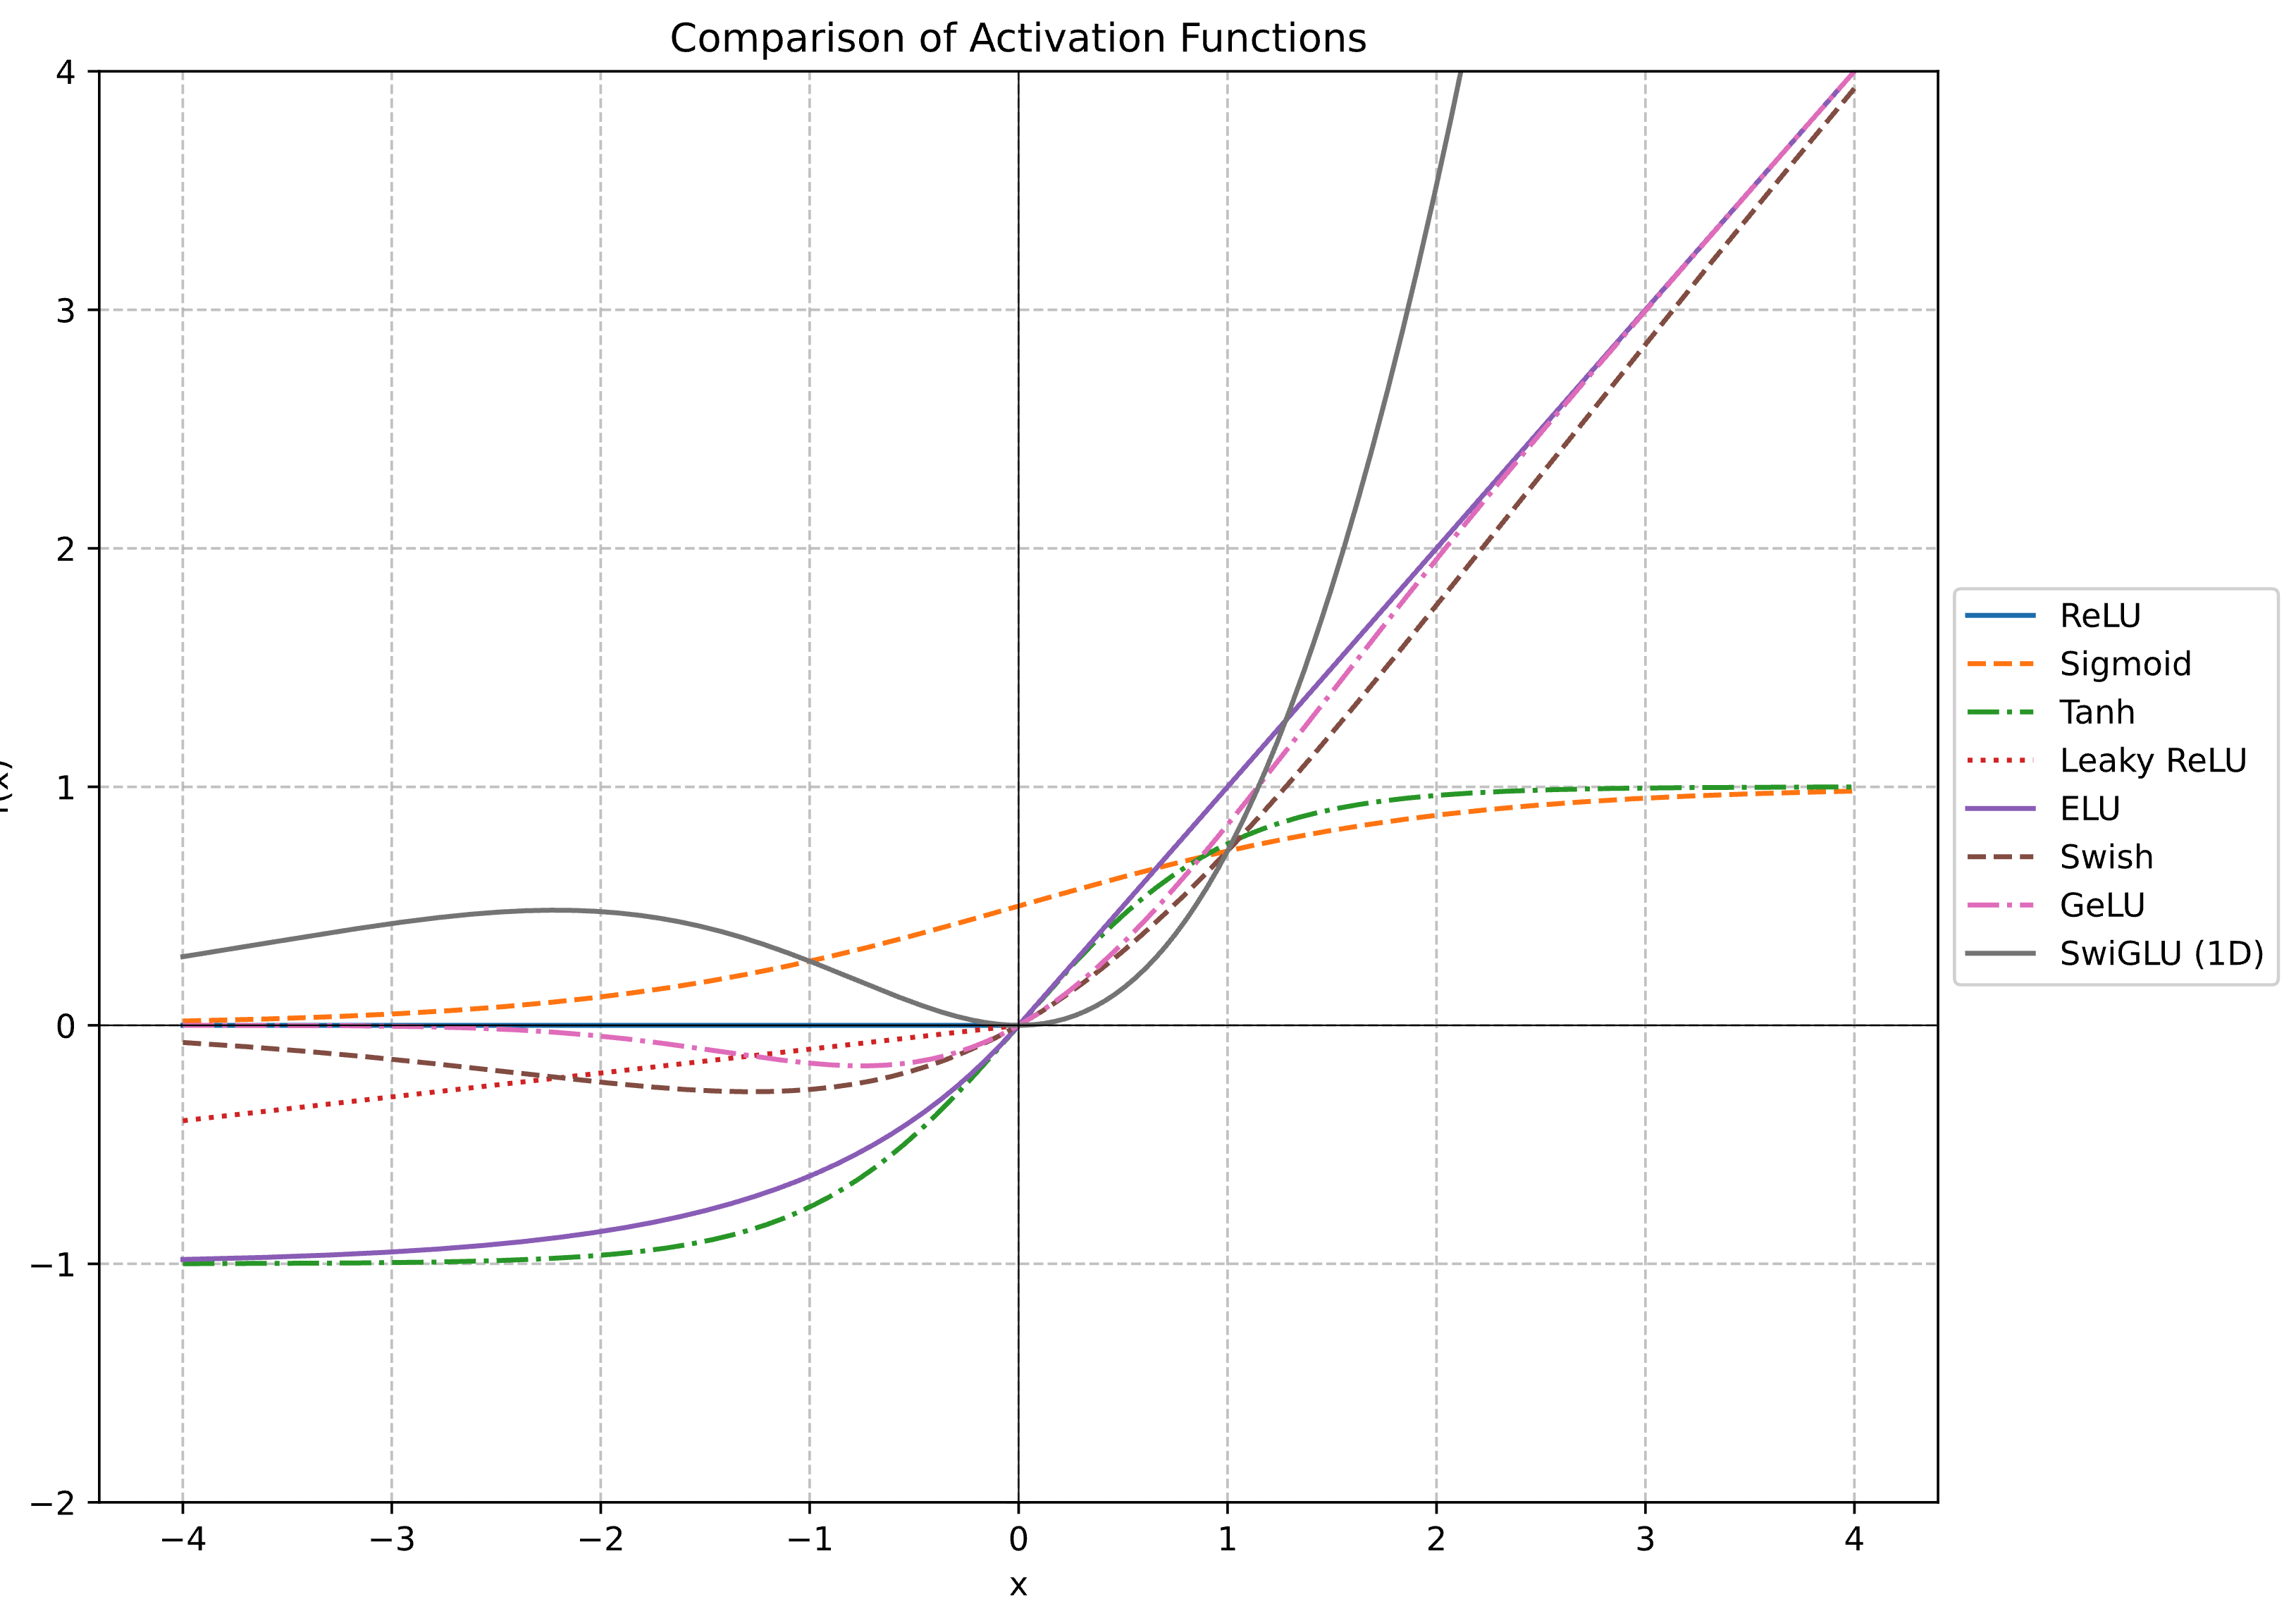
(source: colab)
Details of each activation
GELU
The exact GELU definition is:
GELU(x)=xΦ(x)
where Φ(x) is the standard normal CDF:
Φ(x)=2π1∫−∞xe−t2/2dt
So equivalently:
GELU(x)=2x(1+erf(2x))
because
Φ(x)=21(1+erf(2x))
The commonly used approximation is:
GELU(x)≈2x[1+tanh(π2(x+0.044715x3))]
Intuition:
GELU(x)=xדprobability that a standard Gaussian is≤x”
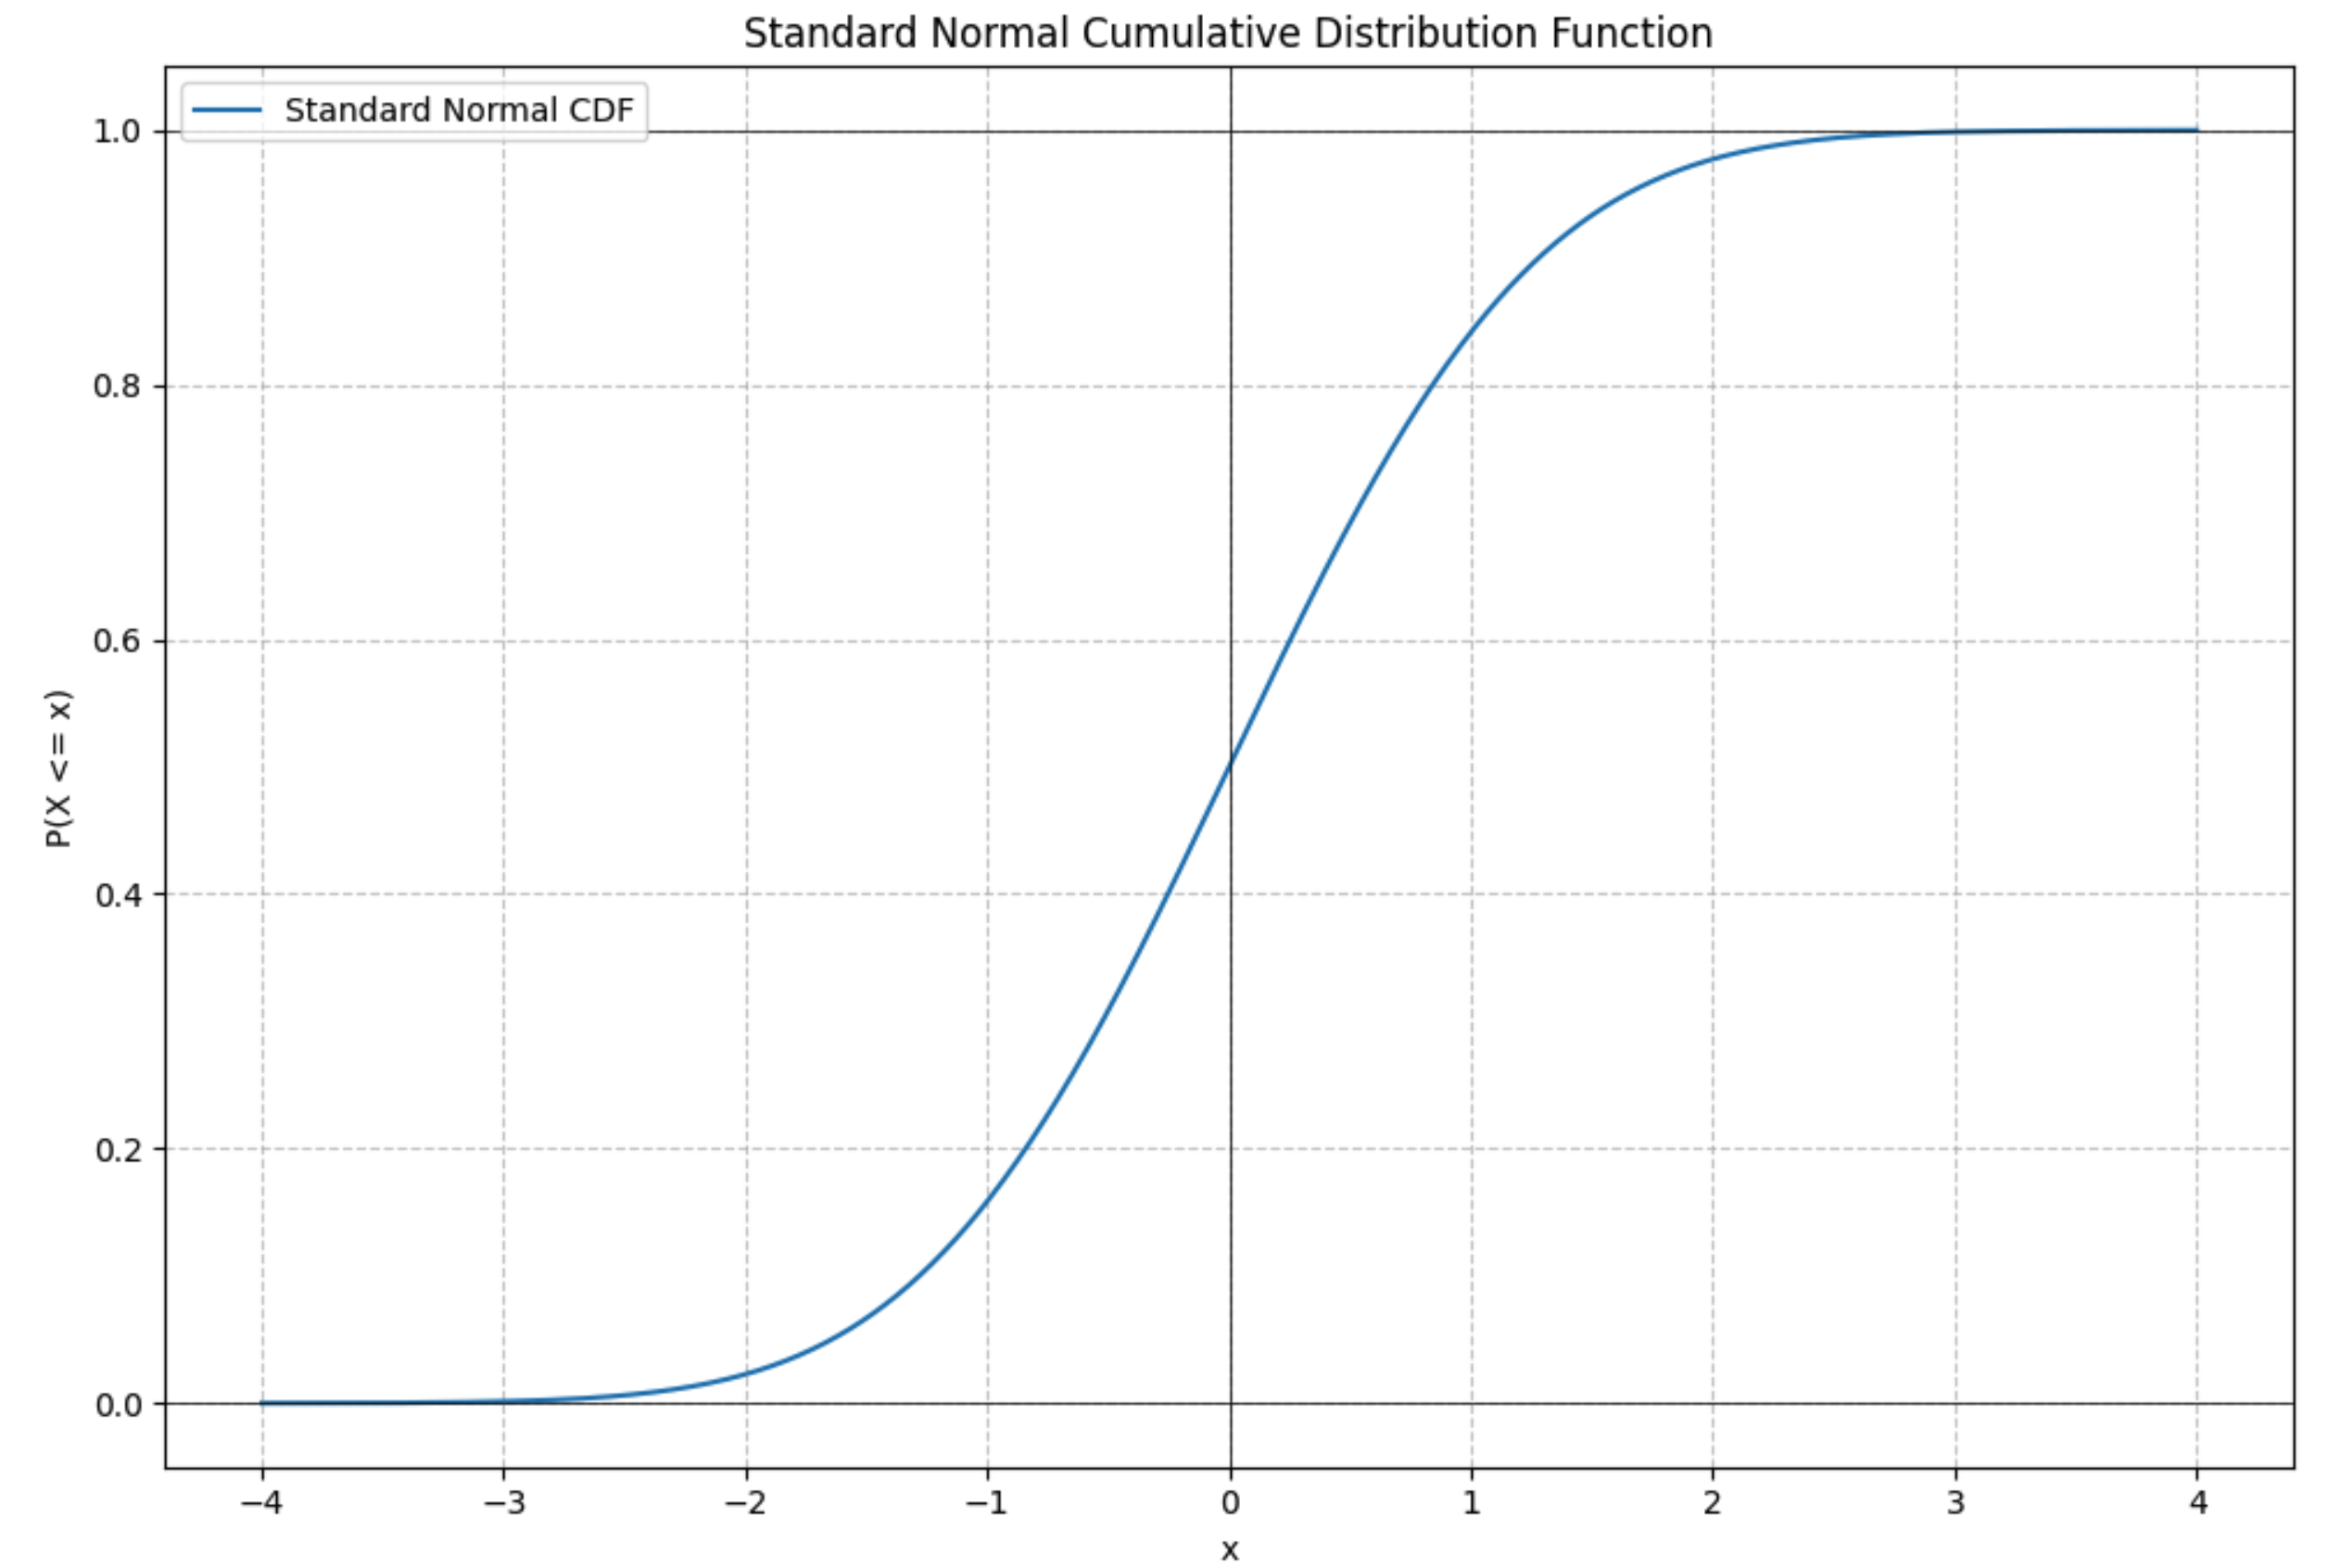
Φ(x)=P(Z≤x), Z∼N(0,1) — as x→−∞, Φ(x)→0; as x→+∞, Φ(x)→1; and Φ(0)=0.5.
SiLU
SiLU stands for Sigmoid Linear Unit.
Its mathematical definition is:
SiLU(x)=xσ(x)
where sigmoid is
σ(x)=1+e−x1
So equivalently:
SiLU(x)=1+e−xx
Gated Activation
Typically inside the Transformer FFN/MLP sublayer, not in the attention operation.
For a modern decoder block, the rough structure is:
x→Attention→FFN / MLP
Inside the FFN, a gated activation like SwiGLU is applied here:
xWg,Wu{xWg SiLU xWu ⊙ hWdoutput
So for SwiGLU:
FFN(x)=[SiLU(xWg)⊙(xWu)]Wd
The gated activation is specifically this part:
SiLU(xWg)⊙(xWu)
It sits between the input/up projections and the down projection.
In code:
gate = gate_proj(x)
up   = up_proj(x)

hidden = F.silu(gate) * up   # gated activation happens here

out = down_proj(hidden)